What it does, and doesn't
Does
Transcribes recorded audio in ~100 languages, detects the language, adds punctuation, produces timestamps, translates non-English speech into English.
Doesn't
Label speakers, run in real time by default, or guarantee accuracy on noisy audio. It can invent text on silence or music.
How Whisper works
- The audio is cut into 30-second pieces and each piece is turned into a spectrogram, a picture of which frequencies are present over time.
- An encoder, a Transformer neural network, reads the spectrogram and turns it into a representation of what was said.
- A decoder writes the text token by token, like a language model. Special tokens tell it the language, whether to transcribe or translate, and where to put timestamps.
- The pieces are joined into one transcript with punctuation and capitalisation.
Because it learned from a very large and varied set of real recordings rather than clean studio speech, Whisper copes well with accents and background noise without extra training.
Whisper versions
| Release | Date | What changed |
|---|---|---|
| Whisper (large) | September 2022 | First open-source release, five model sizes |
| large-v2 | December 2022 | Same size, trained longer; more accurate |
| large-v3 | November 2023 | Better accuracy across many languages |
| large-v3-turbo | October 2024 | Much faster, close to large-v3 accuracy |
Whisper (OpenAI) vs apps and websites called "Whisper AI"
"Whisper AI" usually means OpenAI's model. But because the model is open source, many products use the name: websites such as whisperai.com, Mac and Windows apps such as MacWhisper and WhisperDesktop, and dictation tools. These are separate products from other companies or developers, built on the model. Whether they are free, and where your audio goes, depends on each product, not on Whisper itself.
- The model: free and open source (MIT licence), made by OpenAI.
- OpenAI's API: paid per minute; audio is uploaded to OpenAI.
- Third-party websites and apps: their own prices and privacy terms. Web services upload your audio; local apps keep it on your computer.
Model sizes
| Model | Parameters | Accuracy | Speed | Typical use |
|---|---|---|---|---|
| tiny / base | 39M / 74M | Low | Very fast | Drafts, weak hardware |
| small | 244M | Good | Fast | Laptops without a GPU, clean English |
| medium | 769M | Very good | Moderate | CPU default for most languages |
| large-v3 | 1.55B | Best | Slow without GPU | Accents, jargon, noise; anything with a GPU |
Variants such as large-v3-turbo trade a little accuracy for much higher speed, and distilled versions exist for English. Apps usually let you switch.
Local Whisper vs the Whisper API
The same model, two very different privacy positions. Through the API, your audio is uploaded to OpenAI and billed per minute. Run locally, the audio never leaves your machine and there is no per-minute cost; you pay with compute time instead. A one-hour file takes a few minutes on a modern GPU and about an hour on a CPU.
- Command line: OpenAI's reference implementation, faster-whisper, whisper.cpp, WhisperX with speaker labels. Free, technical.
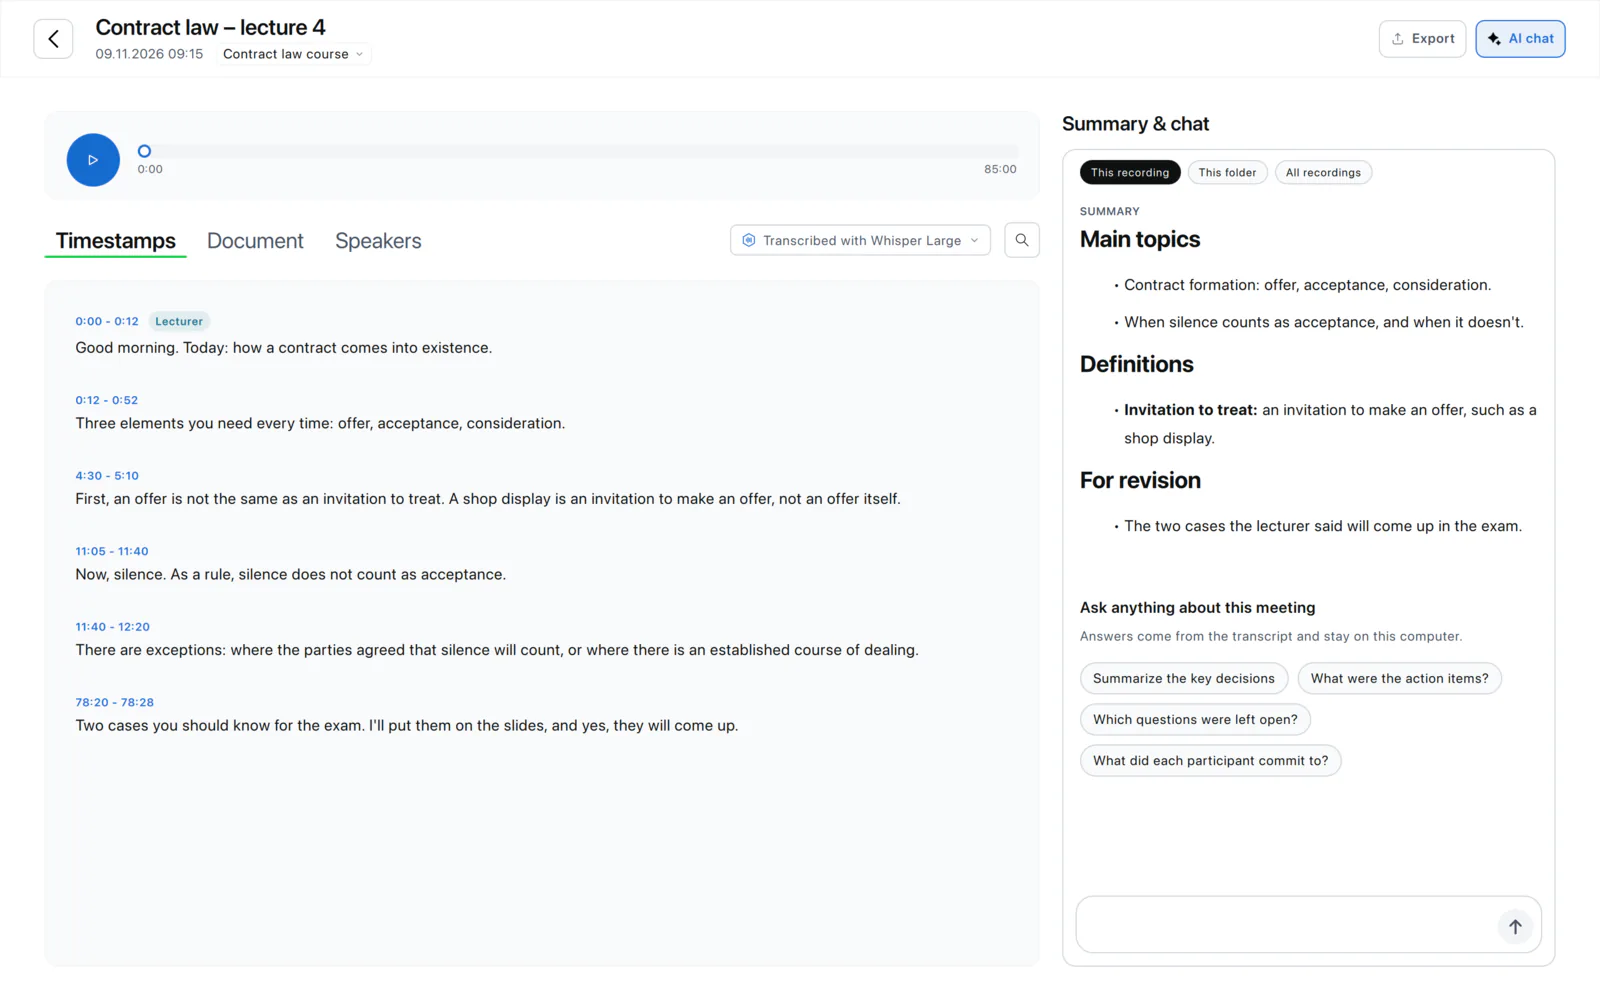
- Desktop apps: MacWhisper on Mac, Buzz on Mac, Windows and Linux (free, with speaker identification), Scrieb on Mac and Windows with speaker identification, summaries and DOCX export.
Comparison of the apps: best local transcription software. What "local" has to mean: local transcription.
Accuracy in practice
On clear recordings of native speakers, large-v3 is close to human-level for most major languages. Accuracy drops with strong accents, domain jargon, crosstalk and low-quality audio. Where the model runs makes no difference: a cloud service using Whisper and a local app using the same model size produce the same text. What differs is who holds the audio.
Try it on your own recordings
Frequently asked questions
- What is Whisper AI used for?
- Turning recorded speech into text: interviews, meetings, lectures, podcasts, voice memos and video subtitles, in about 100 languages. It can also translate speech from other languages into English. Developers build it into transcription apps, note-takers and dictation tools.
- Is Whisper AI owned by OpenAI?
- The Whisper model is made by OpenAI and released as open source. Many apps and websites with "Whisper" in their name, such as whisperai.com, MacWhisper or WhisperDesktop, are separate products by other companies or developers that use the model. They are not OpenAI.
- Is Whisper AI safe to use?
- The model itself is just software: run on your own computer, it sends nothing anywhere. Privacy depends on where it runs. With OpenAI's API or a website that uses Whisper, your audio is uploaded to that service. With a local app, the audio stays on your computer. Download apps only from their official site.
- How do I use Whisper AI for transcription?
- Three ways: the Whisper API (upload to OpenAI, billed per minute), the command line on your own computer (free, needs Python and ffmpeg), or a desktop app that bundles Whisper, such as Buzz or Scrieb, where you drag in a file and get a transcript.
- Is Whisper transcription free?
- The model is open source under the MIT licence and free to download and run. OpenAI also sells access to it through an API, priced per minute of audio, where your audio is uploaded to OpenAI. Running it locally costs nothing beyond your hardware.
- Does Whisper work offline?
- Yes, when you run it on your own computer through the command line or a desktop app. The API version requires an internet connection and uploads the audio.
- Which Whisper model should I use?
- large-v3 for the best accuracy if you have a GPU or patience; medium as the default on CPU-only machines; small or base for quick drafts of clean audio. Bigger models are more accurate and slower.
- Does Whisper identify speakers?
- No. Whisper only produces text. Speaker labels require a separate diarization model run alongside it, which some apps, Scrieb among them, include.
- What is Whisper hallucination?
- On silence, music or very poor audio, Whisper can invent plausible text that was never said, or repeat a phrase. It happens rarely on clear speech. Tools mitigate it with voice activity detection and by trimming silence; a read-through catches the rest.
- Can Whisper transcribe in real time?
- Not by design; it processes chunks of recorded audio. Streaming setups exist but add complexity and lag. For live captions, purpose-built streaming models are better; for recordings, Whisper is the standard.