What diarization produces
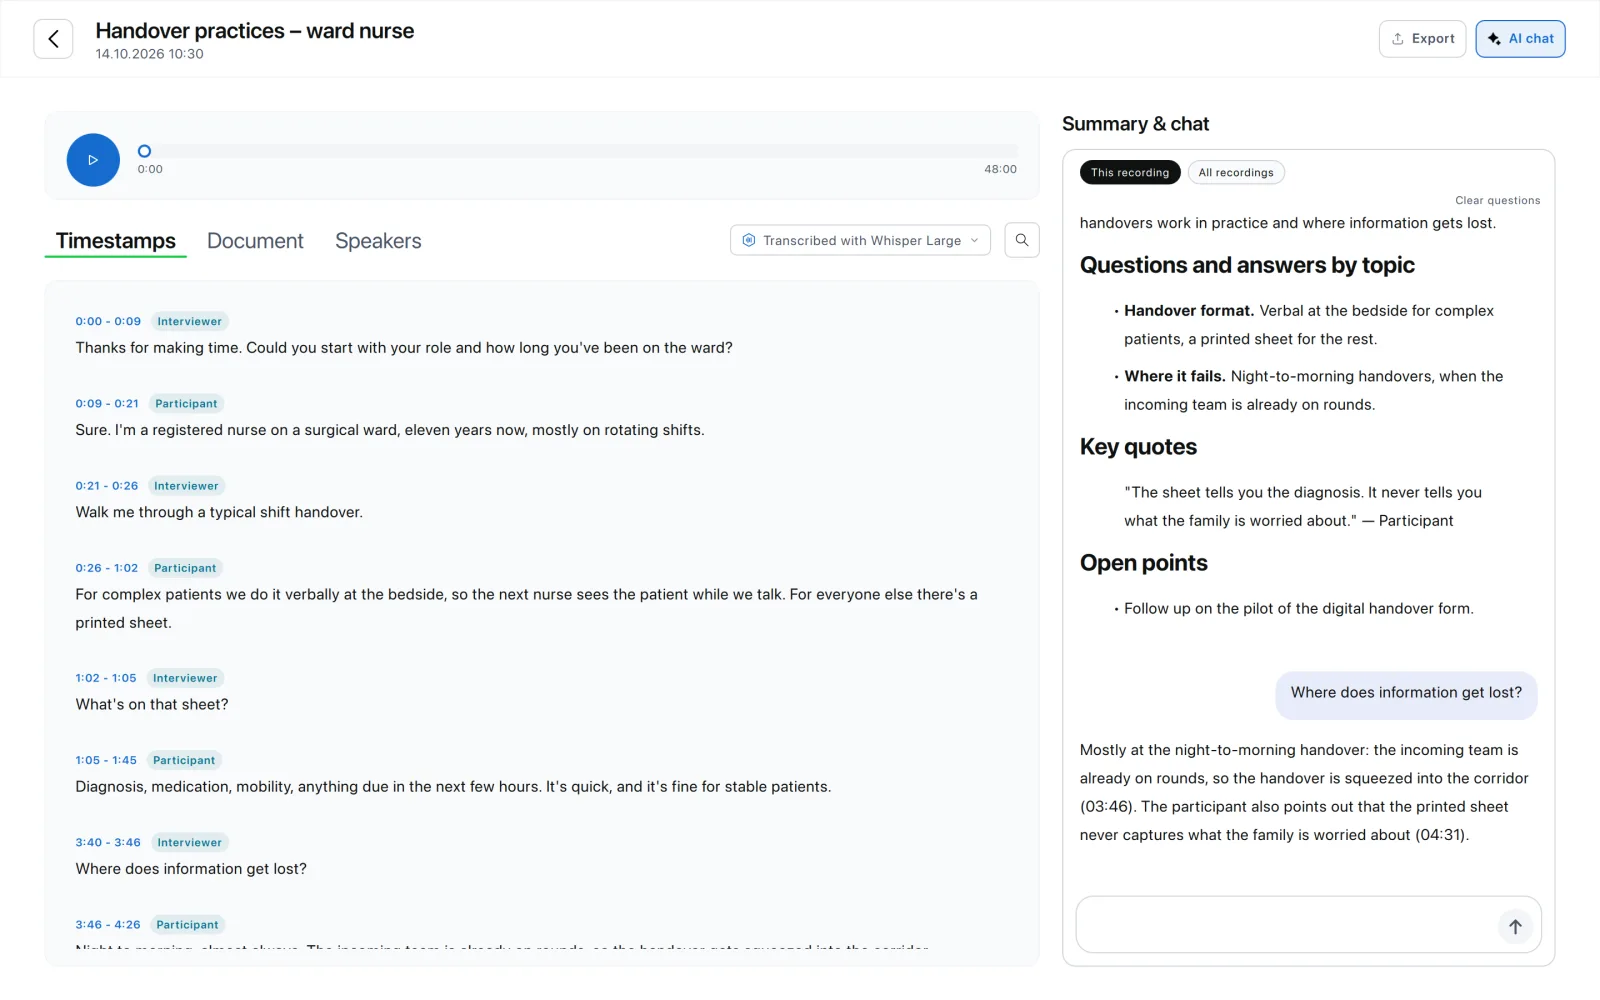
Without it, a transcript of a two-person interview is one block of text. With it, the same transcript reads as:
How it works
- Voice activity detection. Find the parts of the audio where someone is speaking.
- Segmentation. Cut speech into short chunks at likely speaker changes.
- Speaker embeddings. Turn each chunk into a numeric fingerprint of the voice.
- Clustering. Group similar fingerprints; each cluster becomes a speaker label.
- Alignment. Merge the labelled time ranges with the words from speech recognition.
Open-source pipelines such as pyannote implement these steps and are what most local tools, Scrieb included, build on.
The number of speakers: the setting that matters most
Clustering, step 4 above, has to guess how many voices are in the audio file. When it guesses wrong, you see the typical diarization errors: one person split into two labels because their voice changed when they moved away from the microphone, or two similar voices merged into one. Most diarization systems therefore accept a speaker count, either exact or as a minimum and maximum.
| Situation | What to set | Why |
|---|---|---|
| Interview, two people | Exactly 2 | Removes almost all split-speaker errors |
| Meeting, known attendees | The number of people who spoke | Silent attendees do not need a label |
| Panel or workshop | Leave automatic, then correct | Hard to know who will speak |
| Voice memo, one speaker | 1 | Stops background voices getting their own label |
In Scrieb, choosing what a file is on import (interview, meeting, voice memo…) sets how many speakers to look for. If the count is still wrong, set the number of speakers in the Speakers tab and run "Identify again"; renaming a speaker once updates the whole transcript.
Why Whisper doesn't include it
Whisper was trained to map audio to text. It has no representation of who is speaking, so it cannot label turns. Products that advertise "Whisper with speaker labels" are running a second, diarization model and merging the results. That matters for privacy: a tool can run Whisper locally and still send the audio to a server for the diarization step. Ask about both.
What makes it fail
Overlapping speech
Two people at once is the hardest case; most models assign the segment to one of them.
Similar voices
Two speakers of the same pitch and accent may be merged into one label.
Poor audio
A laptop microphone across the room, phone-quality audio or heavy noise blur the voice fingerprints.
Many speakers
Panels of ten sound-alike voices are split unreliably; two to six speakers taking turns is the sweet spot.
Echo on calls
When the other side plays through your speakers, the microphone hears them twice and the echo can be mistaken for a second voice. Scrieb removes that echo after recording.
Wrong speaker count
Automatic counting is the most common source of split or merged speakers. Set the number when you know it.
Practical advice for recordings, and how it runs offline in Scrieb: speaker identification.
Try it on your own recordings
Frequently asked questions
- What does diarization mean?
- Diarization is the task of answering "who spoke when" in a recording: dividing the audio into segments and assigning each segment to a speaker. The output is a set of labels such as Speaker 1 and Speaker 2 attached to time ranges. It comes from "diary", as in keeping a log of turns.
- Is speaker diarization the same as speaker identification?
- Almost. Diarization separates and labels speakers without knowing who they are: Speaker 1, Speaker 2. Speaker identification, strictly, matches a voice to a known person. In transcription apps the terms are used interchangeably for the first thing, and that is how Scrieb uses it: labels by voice.
- Does Whisper do speaker diarization?
- No. OpenAI's Whisper converts speech to text and has no notion of speakers. Diarization requires a separate model, usually a segmentation and speaker-embedding pipeline such as pyannote, run alongside Whisper and merged with its output.
- How accurate is speaker diarization?
- It is measured by diarization error rate, the share of audio attributed to the wrong speaker, missed or falsely detected. On clean recordings with two to six speakers and little overlap, modern models achieve single-digit error rates. Overlapping speech, similar voices and poor audio raise it quickly.
- Can diarization run offline?
- Yes. The models are small enough to run on a laptop CPU or GPU. Scrieb runs diarization locally alongside transcription; WhisperX does the same from the command line. Most cloud services run it on their servers.
- What does "who spoke when" mean?
- It is the question diarization answers. The system does not know names; it finds where speech changes from one voice to another and gives each voice a label, such as Speaker 1 and Speaker 2, with start and end times. You rename the labels to real names afterwards.
- Should I tell the software how many speakers there are?
- If you know, yes. The hardest part of diarization is deciding how many voices there are; telling it removes most errors such as one person split into two labels. In Scrieb you set the number of speakers in the Speakers tab and run "Identify again".
- How many speakers can diarization handle?
- There is no hard limit, but accuracy falls as speakers multiply and voices resemble each other. Two to six speakers who take turns is the range where it works well.