What you need
Windows 10 or 11
x64 (Intel, AMD) or ARM64 (Snapdragon). Scrieb supports both natively; the free tools below and the Python route are x64 only.
RAM
8 GB minimum. 16 GB is comfortable for the large model.
GPU, optional but decisive
NVIDIA RTX 20-series or newer: a one-hour file in 4–12 minutes. CPU only: about an hour for an hour.
Disk
1–3 GB per model, downloaded once. The audio files and transcripts stay wherever you put them.
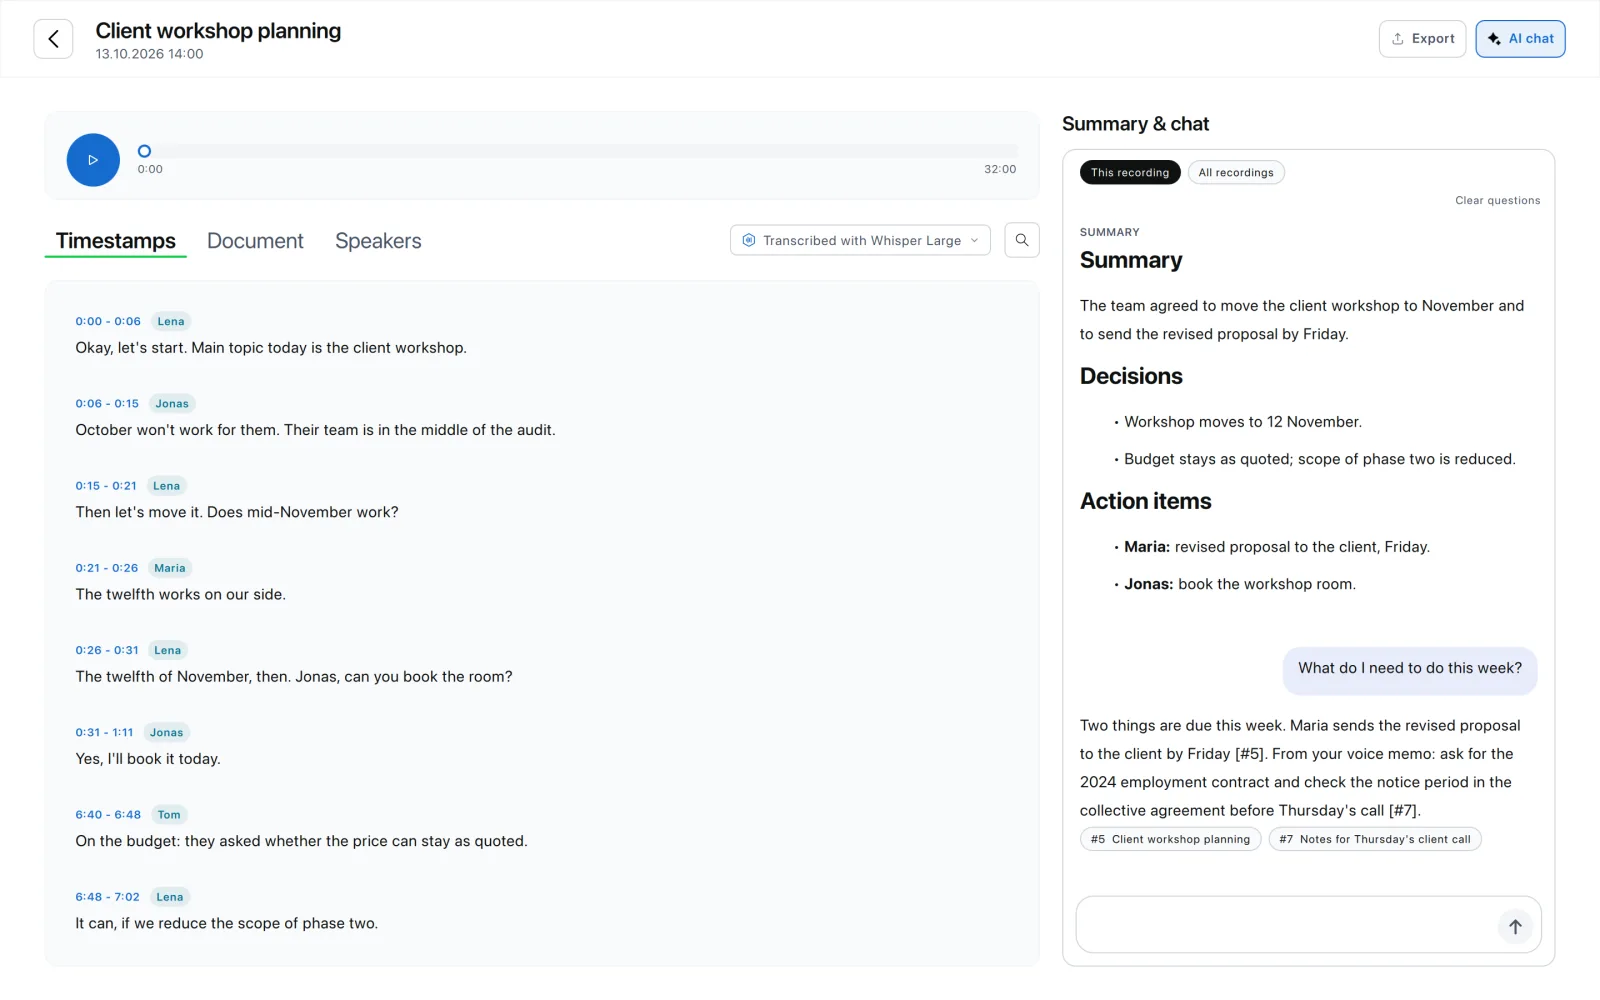
Install Whisper on Windows: desktop app or command line
| Whisper desktop app (Scrieb) | Command line (openai-whisper) | |
|---|---|---|
| Install | Download the installer, run it | Python, ffmpeg, pip, PyTorch |
| Time to first transcript | A few minutes, mostly the model download | About 15–30 minutes the first time |
| Model download | Pick Small, Medium or Large v3 Turbo in Settings; downloads with progress | On first run, into your user folder |
| GPU | Chosen automatically; override under Settings → AI Models → Processing device | Needs the CUDA build of PyTorch (NVIDIA only) |
| Speaker labels, summaries | Included, local | Not included (WhisperX adds speakers) |
| Windows on ARM | Native ARM64 build | x64 only |
Desktop app: three steps
- Download and install the Windows installer (x64, or ARM64 for Snapdragon laptops) from the button on this page.
- Choose a model under Settings → AI Models. It downloads once; after that Whisper runs on your PC.
- Drag in an audio or video file, or start a recording. The transcript, speaker labels and summary appear when it finishes.
The whole route in 1 minute 43 seconds: installer, model download, a file dropped in, the transcript with named speakers and a summary. Also on YouTube.
Command line: the short version
winget install Gyan.FFmpeg
pip install -U openai-whisper
whisper interview.mp3 --model medium --language en
Python 3.10 or 3.11 has to be installed first, and NVIDIA owners need the CUDA build of PyTorch for speed. The full walkthrough is in option 5 below.
The five ways, easiest first
| Setup | Speaker labels | GPU | Price | |
|---|---|---|---|---|
| 1. Scrieb (app) | Installer | ✓ | NVIDIA, AMD, Intel | Free 1 h/day, Pro paid |
| 2. Buzz (app) | Installer | ✓ | NVIDIA | Free |
| 3. WhisperDesktop (GUI) | Unzip + model file | ✗ | Any (DirectCompute) | Free |
| 4. whisper.cpp (binaries) | Unzip + terminal | ✗ | NVIDIA, CPU-optimised | Free |
| 5. Official CLI (Python) | Python + pip + ffmpeg | ✗ (WhisperX adds it) | NVIDIA via CUDA | Free |
Want more free options with a window, such as Vibe, noScribe or aTrain? See the Whisper GUI comparison. Used MacWhisper on a Mac and want the same on your PC? See MacWhisper for Windows. Comparing apps including Mac-only ones? See the best local transcription software comparison.
1. Scrieb: Whisper with no setup, plus speaker labels
Scrieb is a desktop app for Windows and Mac that bundles Whisper, a local diarization model for speaker labels, and a small local model for summaries. Install, drop in an audio or video file, get a transcript that reads as a dialogue, export DOCX, PDF or TXT. Whisper runs on the PC and nothing is uploaded. The free plan checks its daily allowance online before each transcription; with Pro, Scrieb works fully offline. Here is a longer tour:
It is the only option on this page with a paid plan; the free plan gives 1 hour a day. If you only transcribe single-voice recordings and don't mind a terminal, the free routes below are genuinely fine. If you transcribe interviews, meetings or calls and need who-said-what without touching Python, this is the one. Download it free. On a Snapdragon or other ARM64 PC, take the native build instead: download the ARM64 installer.
2. Buzz: free open-source app with speaker labels
Open-source desktop app for Windows, Mac and Linux. Download the installer from the project's GitHub releases, open it, drag in a file, pick a model size, get text. It can use an NVIDIA GPU. It now identifies speakers too. Export is TXT, SRT or VTT, and the Windows installer is unsigned.
3. WhisperDesktop: free GUI that uses any GPU
WhisperDesktop is a Windows-only GUI around whisper.cpp, notable because it uses DirectCompute, so AMD and Intel GPUs accelerate it, not just NVIDIA. Download the zip from the Const-me/Whisper GitHub releases, download a ggml model file, point the app at it. It hasn't been updated since 2023, newer models such as large-v3 give errors, and there are no speaker labels, but on a PC without an NVIDIA card it is still a fast free option. Download links, model files and fixes: WhisperDesktop guide.
4. whisper.cpp: prebuilt binaries, runs well on CPU
The C++ port of Whisper, with Windows binaries on its GitHub releases page. Unzip, download a model, run from a terminal. It wants 16 kHz mono WAV input, so convert first:
ffmpeg -i interview.mp3 -ar 16000 -ac 1 interview.wav
whisper-cli.exe -m ggml-medium.bin -f interview.wav -l en -otxt
The CUDA build on the releases page uses NVIDIA GPUs; the standard build is tuned for CPUs and is the best choice for older laptops.
5. The official command line: step by step
The reference implementation from OpenAI. About fifteen minutes the first time.
- Install Python 3.10 or 3.11 from python.org. Tick "Add Python to PATH" in the installer.
- Install ffmpeg, which Whisper uses to read audio. In a terminal:
winget install Gyan.FFmpeg
Close and reopen the terminal afterwards so PATH updates. - Install Whisper:
pip install -U openai-whisper
- If you have an NVIDIA GPU, install the CUDA build of PyTorch. pip installs the CPU build by default, which is the single most common reason Whisper is slow. Use the command from the selector at pytorch.org for your CUDA version; it looks like:
pip install torch --index-url https://download.pytorch.org/whl/cu121
Then check:python -c "import torch; print(torch.cuda.is_available())"must print True. - Run it:
whisper interview.mp3 --model medium --language en --output_format txt
The first run downloads the model, 1.5 GB for medium, 3 GB for large. Output goes next to the input file as .txt, or .srt and .vtt with other output formats. - Want speaker labels? Install WhisperX instead (
pip install whisperx); it adds diarization but needs a Hugging Face token for the speaker model and the same CUDA setup.
A faster drop-in for the same workflow is faster-whisper, which uses less memory and runs the large model on smaller GPUs.
Errors everyone hits
"ffmpeg not found" / FileNotFoundError
ffmpeg is not on PATH. Install it with winget, then open a new terminal window; the old one keeps the old PATH.
It runs, but very slowly
torch.cuda.is_available() returns False: the CPU build of PyTorch is installed. Uninstall torch and install the CUDA build from pytorch.org.
"FP16 is not supported on CPU; using FP32 instead"
Harmless. It just means no GPU was found. Add --fp16 False to silence it, or fix the GPU setup.
First run hangs for minutes
It is downloading the model to %USERPROFILE%\.cache\whisper. Wait, or pre-download on a fast connection.
Invented sentences during silence or music
Whisper hallucinates on non-speech. Trim silence first, or use an app with voice-activity detection in front of the model.
Out of memory on large
Use medium, or large-v3-turbo, or faster-whisper with int8 compute. The large model needs about 10 GB of VRAM in the official build.
Which model on which hardware
| Model | Accuracy | CPU-only PC | NVIDIA GPU |
|---|---|---|---|
| tiny / base | Low | Fast, drafts only | Instant |
| small | Good | Usable, ~2× real time | Very fast |
| medium | Very good | About real time; the CPU default | Fast |
| large-v3 | Best | Too slow for daily use | The default with a GPU |
| large-v3-turbo | Near large-v3 | Slow | Fastest high-accuracy option |
October 2026 update: since version 0.7.0, Scrieb lets you switch between Whisper Small, Medium and Large v3 Turbo under Settings, downloads the one you pick on the spot, and can re-transcribe an existing recording with a different model while keeping the earlier transcript for comparison. That makes the table above a setting rather than a reinstall: start with Medium on a CPU-only laptop, move to Large v3 Turbo once you have a GPU. Since version 1.0 it also skips silence before Whisper sees it, so the model no longer invents text in pauses, and lets you set the spoken language by hand when detection gets it wrong.
Pricing
Whisper with speaker labels and no setup. Free plan: 1 hour of recording a day. Pro: no minute limits, one licence for Windows and Mac.
Try it on your own recordings
Frequently asked questions
- Does Whisper work on Windows?
- Yes. OpenAI's Whisper runs on Windows 10 and 11 through Python, through the whisper.cpp binaries, or inside desktop apps that bundle it. Everything on this page runs locally; the audio never leaves the PC.
- Does Whisper need a GPU on Windows?
- No, but it helps a lot. On CPU alone the medium model runs at roughly real time: a one-hour file takes about an hour. With an NVIDIA RTX 20-series or newer it runs 5 to 15 times faster. AMD and Intel GPUs work with whisper.cpp and with some apps; the official Python version is NVIDIA-only for GPU acceleration.
- Is there a Whisper GUI for Windows?
- Several. Scrieb is a full desktop app with speaker labels and DOCX export; Buzz is a free open-source app; WhisperDesktop is a free GUI around whisper.cpp that also uses AMD and Intel GPUs. Buzz also labels speakers; WhisperDesktop does not.
- Is Whisper free?
- The model is open source and free. Running it costs nothing beyond your hardware. Paid apps like Scrieb charge for the interface, speaker identification, summaries and support, not for Whisper itself.
- Which Whisper model should I use on Windows?
- large-v3 if you have an NVIDIA GPU; medium on CPU-only machines; small for quick drafts of clean English audio. The turbo variant of large-v3 is a good middle ground on GPUs.
- Can Whisper identify speakers?
- Not by itself. Whisper produces text only. Speaker labels need a separate diarization model. On Windows, Scrieb and Buzz run that step locally in an app; WhisperX does it from the command line; WhisperDesktop and the official CLI don't label speakers.
- Why is Whisper so slow on my PC?
- Almost always one of three things: it is running on CPU because the CPU-only build of PyTorch was installed, the model is larger than the machine can handle, or the file is being processed in a single pass with a large model on little RAM. Check torch.cuda.is_available() first.